JSON-Structured Prompts vs. Natural-Language Prompts: When Structure Helps and When It Gets in the Way
October 9, 2026 · 10 min read
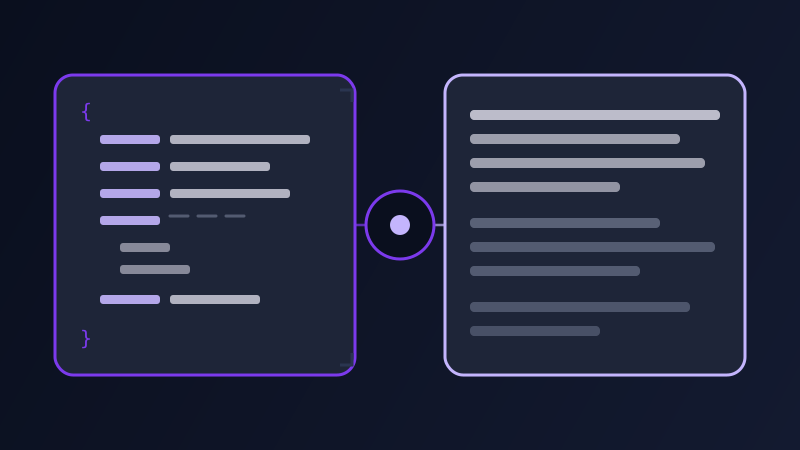
Somewhere in the last couple of years, a piece of advice started circulating that sounded like a clean upgrade to prompting: stop writing prompts as paragraphs, write them as JSON. Give the model a schema. Treat it like an API call instead of a conversation. It is genuinely good advice for a specific category of task, and genuinely bad advice for another category right next to it, and most of the frustration people run into with structured prompting comes from applying it to the wrong one. The two formats are not a strictly-better and strictly-worse pair. They are two different interfaces for the same underlying model, and each one trades something away to get something else.
Two different ways to hand a model the same request
A natural-language prompt reads like something you would say to a competent colleague: "Write a two-paragraph product description for a stainless steel water bottle, aimed at outdoor enthusiasts, in an upbeat but not cheesy tone." A structured prompt hands the model the same request as discrete fields: {"task": "product_description", "product": "stainless steel water bottle", "audience": "outdoor enthusiasts", "tone": "upbeat, not cheesy", "length": "two paragraphs"}. Both versions contain the same information. The difference is in how that information is organized, and organization changes how the model has to process it. Prose asks the model to parse meaning out of a flowing sentence the way it would from any other text it was trained on. A JSON object asks the model to treat each field as an independent, labeled unit, closer to filling out a form than reading a sentence.
Where structure genuinely helps: extraction, pipelines, and anything downstream reads
Structured prompting earns its reputation in a specific family of tasks: anything where the output has to be parsed by another piece of software rather than read by a person. Asking a model to pull every invoice number, date, and total from a batch of receipts and return them as an array of objects is a task that wants JSON on both ends, because the input is naturally tabular and the output is about to be fed into a database or a spreadsheet, not read for tone. The same logic applies to classification tasks (sentiment, category, intent), to tool-calling and agent workflows where the model's output triggers a specific function with specific arguments, and to any prompt that runs in a loop over hundreds or thousands of similar items, where even a small amount of formatting inconsistency across outputs becomes a real parsing problem at scale. In all of these cases, structure is not a style preference, it is a contract: the field names tell the model exactly what goes where, and a schema removes the ambiguity that would otherwise creep in when the same instruction gets interpreted slightly differently on the fortieth item versus the fourth.
Structure also helps on prompts with many independent, easy-to-drop constraints. A natural-language paragraph that tries to specify role, audience, tone, length, format, and three things to avoid, all in flowing prose, is exactly the kind of prompt where one constraint quietly gets dropped or blended into another, because nothing in the sentence structure marks it as a separate, equally weighted requirement. Breaking the same six constraints into six labeled fields gives each one its own slot, and a model is noticeably less likely to silently skip a field with its own label than a clause buried in the middle of a long sentence.
Where structure backfires: reasoning, nuance, and anything creative
The failure mode runs the other way on tasks that are fundamentally about judgment rather than retrieval. Ask a model to write a eulogy, brainstorm five taglines, reason through a tricky ethical tradeoff, or give feedback on a piece of writing, and forcing that request into rigid key-value fields tends to produce flatter, more mechanical output than the same request written as a paragraph. Creative and reasoning tasks benefit from the connective tissue that prose provides, the "because," the "even though," the implied relationship between one constraint and another, and JSON strips exactly that connective tissue out by design. A field like "tone": "bittersweet" sitting next to "length": "150 words" gives the model two isolated facts. A sentence like "keep it bittersweet rather than sad, since this needs to end on something the reader can smile at despite the loss" gives the model a reason, and reasons are what a model actually uses to make the hundreds of small judgment calls a creative or nuanced piece of writing requires.
Structure also backfires simply by being brittle on open-ended requests. A JSON schema implicitly tells the model that the task has a fixed, enumerable shape, which is false for most creative and strategic work. Forcing "what should our Q3 content strategy focus on" into predefined fields like {"topic": "", "format": "", "channel": ""} pre-decides the shape of the answer before the model has had a chance to reason about whether that is even the right shape, and the model will dutifully fill in those three fields instead of pointing out that the real answer might require a different structure entirely.
What 'JSON mode' actually guarantees, and what it doesn't
ChatGPT, Claude, and Gemini all now offer some version of constrained or schema-enforced output, commonly called JSON mode, structured outputs, or function calling, depending on the provider. It's worth being precise about what that feature actually does, because it is widely misunderstood as a quality upgrade rather than what it really is: a formatting guarantee. These modes use constrained decoding to force the model's output to match valid JSON syntax, and in the strictest implementations, to match a specific schema's field names and types exactly. What they do not do is make the model reason any better about what belongs in each field. A model given a rigid schema for a task it is bad at will produce perfectly valid, syntactically correct JSON that is just as wrong, or just as shallow, as a plain-text answer to the same weak prompt would have been. Structured output modes solve a parsing problem, not a reasoning problem, and treating a schema as a substitute for a clearly written, well-reasoned prompt is one of the more common mistakes once a workflow starts relying on them.
The hybrid middle ground: labeled sections without going full JSON
The most useful pattern for long, constraint-heavy prompts is often neither pure prose nor strict JSON, but a lighter structure in between: labeled sections, written with simple tags or headers, that keep each major instruction visually separated while still allowing full sentences inside each one. Something like a block labeled CONTEXT followed by a paragraph, a block labeled TASK followed by a paragraph, and a block labeled CONSTRAINTS followed by a short list, gives a long prompt the same benefit JSON gives for keeping instructions from blending into each other, a clear boundary around each piece, without forcing nuanced instructions into a flat key-value pair that can't hold a reason or an exception. This pattern also tends to survive editing better than true JSON: adding a sentence of extra context to a labeled paragraph is trivial, where adding the same nuance to a JSON field without breaking its structure or its parseability is not.
A simple way to decide which one you need
The deciding question is not which format is more advanced, it's whether anything downstream of the model's response needs to parse that response programmatically, and whether the task itself has a genuinely fixed, enumerable shape. If the output feeds a database, a function call, a spreadsheet, or a loop processing many similar items, structure is doing real work and is worth the rigidity it costs. If a person is going to read the output and judge it for tone, persuasiveness, correctness of reasoning, or creative quality, prose, or at most the labeled-section hybrid, almost always produces a better result, because the task was never actually shaped like a form in the first place.
Common mistakes
Reaching for JSON on a creative or strategic prompt because it feels more rigorous, when the task has no natural tabular shape to begin with. Assuming a model's 'JSON mode' or structured-output feature makes its answers more accurate, when it only guarantees the syntax is parseable. Writing a schema with vague field names like "details" or "info" that give the model no more guidance than a blank line would. Cramming a long, nuanced instruction into a single JSON string value instead of either writing it as its own labeled section or breaking it into real sub-fields. And building an extraction or classification pipeline in plain prose, then being surprised when output formatting drifts slightly from one run to the next across a large batch, exactly the failure structure exists to prevent.
Where Promptima handles this
Deciding whether a given request is a parsing problem, a reasoning problem, or something in between isn't always obvious from the task description alone, and getting it wrong in either direction costs you either a broken pipeline or a flattened, mechanical piece of writing. Promptima's text prompt optimizer reads what kind of task you're asking for and builds the prompt accordingly: structured fields and explicit schemas for extraction, classification, and pipeline-style requests that need consistent, parseable output, and full, reasoned prose, or labeled sections for longer constraint lists, for anything that depends on tone, nuance, or judgment.
Frequently asked questions
Does writing a prompt in JSON make an AI model give better answers?
Not on its own. JSON structure helps a model keep track of many independent constraints without blending or dropping one, and it makes the output easier to parse programmatically. It does not improve the model's reasoning, creativity, or judgment, and a weak prompt produces an equally weak answer whether it's formatted as JSON or as a paragraph.
What does 'JSON mode' or 'structured outputs' in ChatGPT, Claude, or Gemini actually guarantee?
It guarantees the output is syntactically valid JSON, and in stricter implementations, that it matches a specific schema's field names and types. It is a formatting guarantee enforced through constrained decoding, not a quality or accuracy guarantee. The model can still fill a perfectly valid field with a shallow or wrong answer.
When should I use natural language instead of a structured prompt?
Whenever the task depends on nuance, reasoning, or creative judgment rather than fixed data retrieval: writing, brainstorming, feedback, strategy, anything where the relationships between constraints (why one matters more than another, when an exception applies) carry real information that a flat key-value field can't hold.
What's a good middle ground between full JSON and plain prose?
Labeled sections: breaking a long prompt into clearly marked blocks like context, task, and constraints, each written as full sentences rather than single-word field values. This keeps instructions from blending together the way they can in a long paragraph, while still letting each section hold a full reasoned explanation instead of an isolated fact.
When is structured prompting worth the rigidity it adds?
When something downstream of the model needs to parse the response automatically, a database, a function call, a spreadsheet, or a batch pipeline processing many similar items, or when the task has a genuinely fixed, enumerable shape like extracting specific fields from a document. In those cases the rigidity is the point: it's what keeps formatting consistent across hundreds of runs.
Try Promptima's text prompt optimizer — it structures a prompt into clean fields when the task is extraction or a pipeline step, and keeps it as flowing prose when the task is reasoning or creative writing, instead of forcing one format on everything →
✦ Try Promptima freeMore articles
Best AI Prompt Optimizer Tools in 2026 (And When to Use Each)
Prompt marketplaces, browser extensions, manual prompt engineering, and dedicated optimizers all solve a different version of the same problem. Here is how to tell which one you actually need.
How to Turn One Photo Into a Ready-to-Use AI Video Prompt
You have an image whose look you want to bring to life as a video. The problem is that video AI tools don’t read image prompts — they need camera, motion, and duration described in a completely different structure. Here’s how to bridge the two.