Tag-Based vs. Natural-Language Prompts: Why Some AI Image Tools Want Keywords and Others Want Sentences
September 25, 2026 · 9 min read
Move a prompt that worked well in one AI image tool over to another and the result often comes back noticeably worse, and the usual conclusion is that the second tool is "worse at prompts." Most of the time that is the wrong diagnosis. The prompt is the wrong shape for what that tool actually learned to read. Two prompting conventions dominate AI image generation, and they are not interchangeable dialects of the same language so much as two different languages entirely: dense, comma-separated keyword tags on one side, and full descriptive sentences on the other. A tool trained to read one gets noticeably worse at understanding the other, no matter how carefully the prompt is written.
Two prompting languages, not one
The split traces back to how each tool actually learned to associate text with images. Tag-based prompting descends from the Stable Diffusion checkpoint community, where countless fine-tuned models were trained or further tuned on image sets labeled with dense strings of short descriptor tags — a convention borrowed directly from art-cataloguing sites that tag images with keywords rather than sentences (subject tags, medium tags, artist-style tags, quality boilerplate like "masterpiece, best quality"). Natural-language prompting descends from tools trained primarily on image-caption pairs, where the caption is an actual sentence describing the photo the way one person would describe it to another. Neither convention is objectively better. Each is legible to the specific kind of model that learned from that shape of text, and each gets visibly worse on a model trained on the other shape.
Where tag-based prompting comes from, and what it actually looks like
A prompt written for a tag-trained checkpoint reads like a keyword list, not a sentence: "1970s red bicycle, rust details, brick wall background, afternoon light, film photograph, shallow depth of field, detailed, masterpiece, best quality." Grammar plays no role, because the model was never trained to parse subject-verb-object relationships — it was trained to associate each tag with regions of the image independently, based on which tags co-occurred with which visual features across the training set. Order still matters, because most tag-trained checkpoints weight earlier tags more heavily than later ones, and syntax like parentheses or colon-based weighting (used to push a specific tag harder or softer) is a real, learned control surface here in a way it usually is not on caption-trained tools. Quality-boilerplate tags at the end ("best quality," "8k," "trending on artstation") function as a learned shorthand for "render this carefully," not as literal instructions the model reasons about.
Where natural-language prompting comes from, and what it actually looks like
Tools trained substantially on captioned photo datasets — where the caption is a real descriptive sentence rather than a tag string — read prompts differently. A sentence like "a weathered red bicycle leans against a sunlit brick wall on a quiet afternoon street, shot on film with a shallow depth of field" tends to outperform the equivalent tag list on these tools, because the model has learned to weigh how words modify and relate to each other in something closer to sentence order, not just which keywords tend to co-occur in a dataset. Feed a comma-separated tag dump into one of these tools and it often addresses each tag as a separate, disconnected instruction rather than integrating them into one coherent scene — the model was never trained to read a tag list as fragments of a single description, so it does not reliably treat it as one.
What happens when you use the wrong style on the wrong tool
The failure modes run in both directions and are easy to misdiagnose as the tool being unreliable rather than the prompt being mismatched. A tag list fed into a caption-trained tool tends to produce a busy, disjointed image that half-addresses every tag without committing to a coherent composition, and quality-boilerplate tags occasionally get rendered as literal, garbled text somewhere in the frame, since the model has no learned association for them as an instruction. A full sentence fed into a tag-trained checkpoint tends to get parsed for its nouns and adjectives while losing the relationships between them — "a fox chasing a rabbit" and "a rabbit chasing a fox" can produce visually similar results, because the checkpoint is responding to which words appeared, not to the sentence structure connecting them, in a way a caption-trained model specifically was trained not to do.
The middle ground most people actually use without naming it
Some of the most widely used image tools sit between the two poles rather than at either extreme: comma-separated phrases instead of single keywords, and instead of a full grammatical sentence. A prompt like "weathered fisherman mending nets on a wooden dock, oil painting, warm golden hour light, low angle shot" is neither a tag dump nor a sentence — each comma-separated segment is a short descriptive phrase, closer to a caption that has been broken into clauses than to either extreme. This hybrid works because these tools were generally trained on a broader mix of captioned data, some of it naturally phrase-heavy, and because their parameter systems (aspect ratio flags, style toggles) are designed to sit entirely outside the descriptive text rather than inside it, so the description itself only has to carry the visual idea.
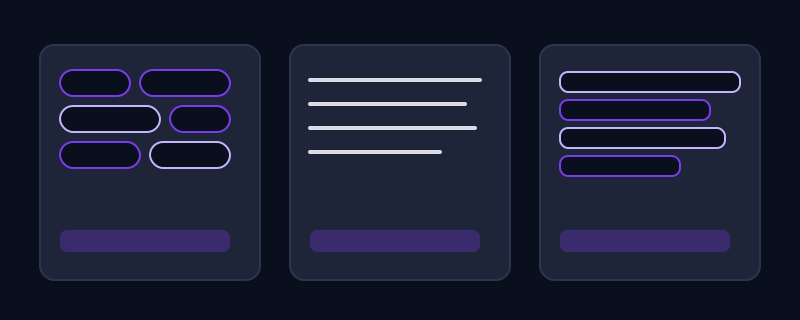
A worked example: the same idea, written three ways
Idea: a red vintage bicycle leaning against a weathered blue wall in soft afternoon light. Tag-style, for a tag-trained checkpoint: "vintage bicycle, red paint, rust details, leaning against wall, blue wall, afternoon light, soft shadow, photorealistic, detailed, 35mm photograph, film grain, best quality." Natural language, for a caption-trained tool: "A red vintage bicycle with visible rust leans against a weathered blue wall in soft afternoon light, casting a long shadow, captured as a realistic 35mm photograph with subtle film grain." Comma-phrase hybrid, for a tool that expects that middle style: "red vintage bicycle leaning against a weathered blue wall, soft afternoon light, long shadow, 35mm photograph, film grain." Same underlying idea, three genuinely different pieces of text, each shaped for what its target tool actually learned to read.
How to tell which style a tool wants before you write anything
Rather than guessing from whatever convention worked in a different tool, check that specific tool’s own documentation or example prompts first. If the examples read as long strings of short comma-separated keywords, frequently ending in quality boilerplate, it is tag-trained — match that shape and treat weighting syntax as a real control, not decoration. If the examples read as full sentences describing a scene the way a caption would, write full sentences and let relationships between elements do the work a tag list cannot. If the examples fall somewhere between — descriptive phrases separated by commas rather than single words or full grammar — use the hybrid style rather than forcing it to either extreme. That one check, before writing the actual prompt, prevents more failed generations than any single wording trick applied afterward.
Common mistakes
Assuming one universal "good prompt format" exists and pasting the same text unchanged into every tool, regardless of what each one was actually trained to read. Carrying tag-style quality boilerplate ("masterpiece, best quality, 8k, trending on artstation") into a caption-trained tool where it does nothing useful and occasionally renders as garbled literal text. Writing a full descriptive paragraph for a tag-trained checkpoint and being confused when specific relationships between elements in the sentence get ignored. Never checking a new or unfamiliar tool’s own example prompts before writing one, and concluding the tool is unreliable when the real issue is a prompt shaped for a different model entirely.
Frequently asked questions
What is the difference between tag-based and natural-language AI image prompts?
Tag-based prompts are dense, comma-separated strings of short keywords — a convention from Stable Diffusion checkpoints trained on tag-labeled image sets, where grammar plays no role and each tag is read almost independently. Natural-language prompts are full descriptive sentences, a convention from tools trained on caption-labeled photo datasets, where the model reads relationships between words in something closer to sentence order. The same idea needs to be written differently for each.
Do I need different prompting skills for Stable Diffusion checkpoints versus tools like Midjourney or DALL-E?
Largely yes, because the two are trained on different shapes of labeled data. Community Stable Diffusion checkpoints typically respond best to comma-separated keyword tags with optional weighting syntax, while caption-trained tools respond best to full sentences or comma-separated descriptive phrases. Checking a specific tool’s own example prompts before writing one is more reliable than assuming either convention carries over.
Does mixing tags and full sentences in one prompt ever work?
It can work as a middle-ground style on tools trained on a broader, more phrase-heavy mix of captioned data — comma-separated descriptive phrases rather than single keywords or full grammatical sentences. But deliberately mixing dense tag boilerplate with full sentences on a tool that expects one or the other consistently tends to confuse both conventions at once rather than getting the benefit of either.
How can I tell which prompting style a new AI image tool expects?
Check that tool’s own documentation or example prompts before writing anything. Long strings of short comma-separated keywords ending in quality boilerplate signal a tag-trained tool; full descriptive sentences signal a caption-trained tool; comma-separated phrases that are not full sentences and not single keywords signal the hybrid middle ground. Matching that shape from the start prevents far more failed generations than adjusting wording after a weak result.
Try Promptima’s prompt optimizer — it writes tag-style prompts for tag-trained tools and full sentences for the rest, automatically →
✦ Try Promptima freeMore articles
Best AI Prompt Optimizer Tools in 2026 (And When to Use Each)
Prompt marketplaces, browser extensions, manual prompt engineering, and dedicated optimizers all solve a different version of the same problem. Here is how to tell which one you actually need.
How to Turn One Photo Into a Ready-to-Use AI Video Prompt
You have an image whose look you want to bring to life as a video. The problem is that video AI tools don’t read image prompts — they need camera, motion, and duration described in a completely different structure. Here’s how to bridge the two.